MARSAD / CONSOLIDATED CATALOG / #020
Eastbound sidewalk chase with backpack retrieval
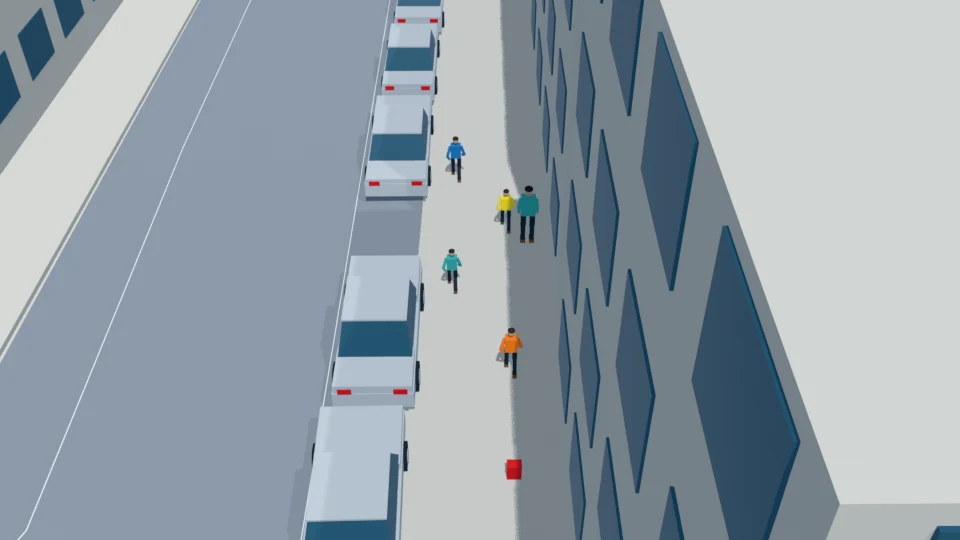
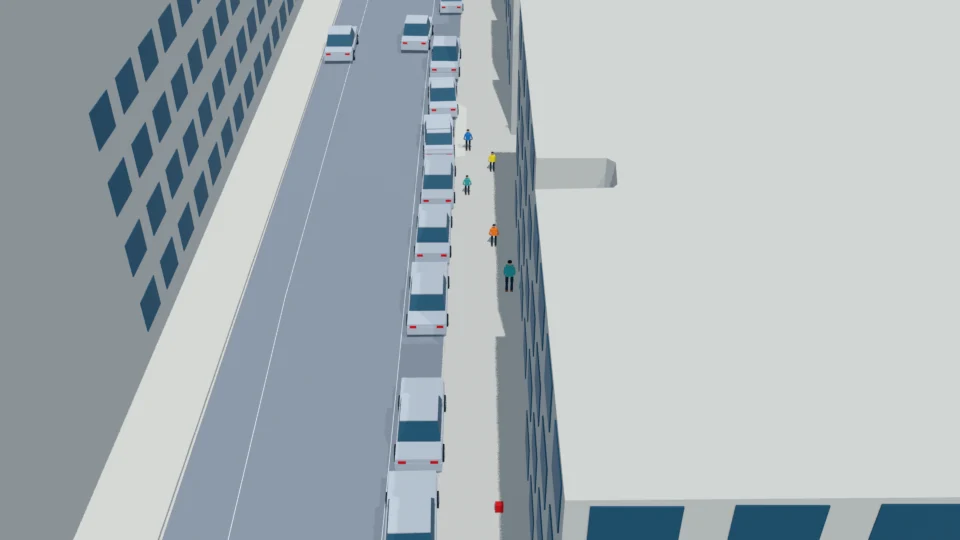
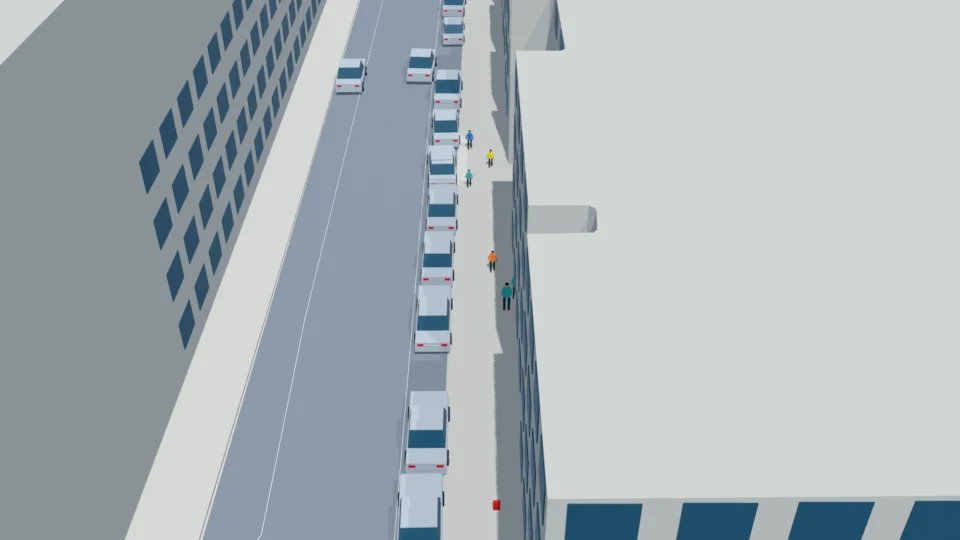
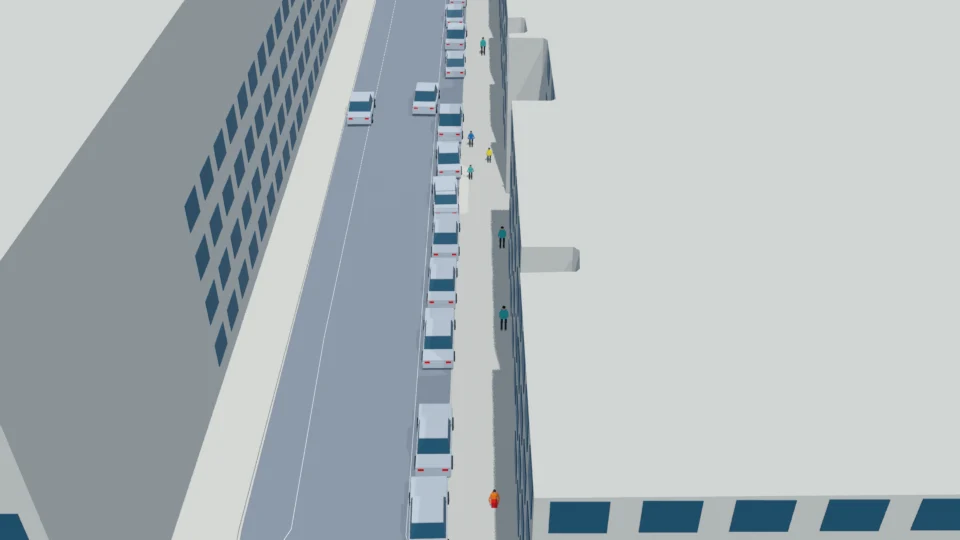
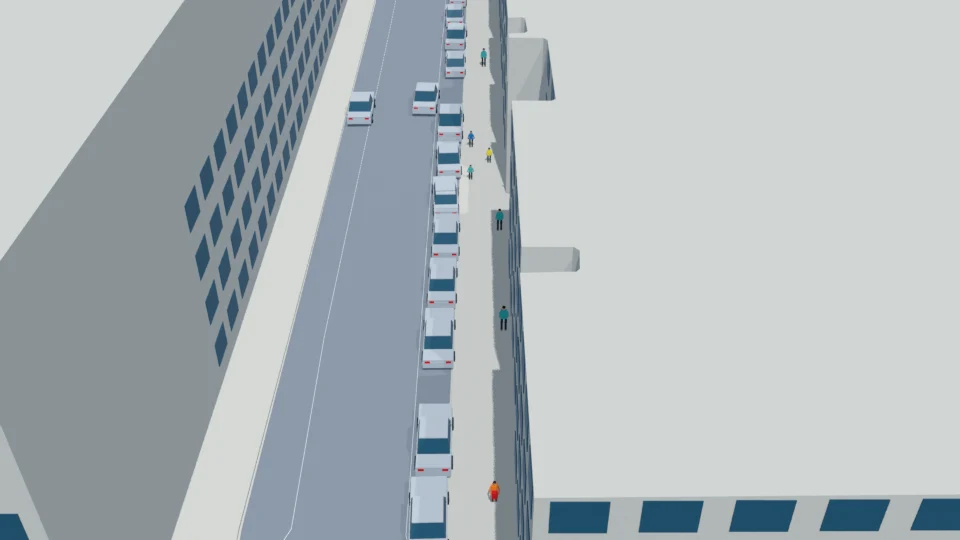
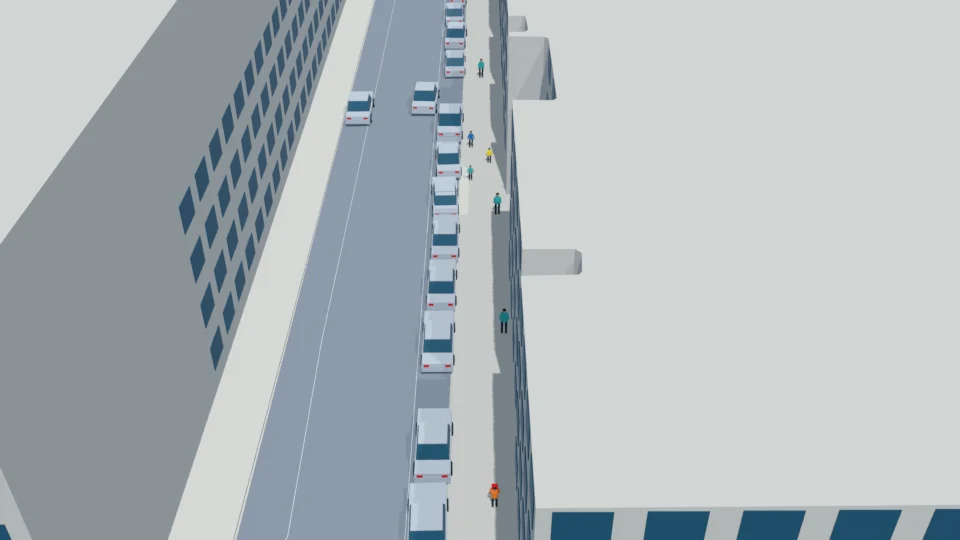
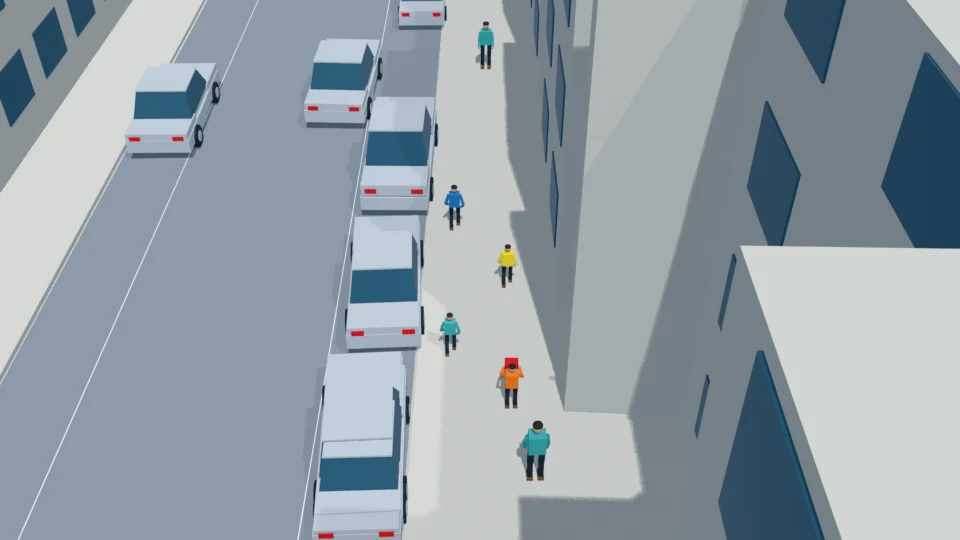
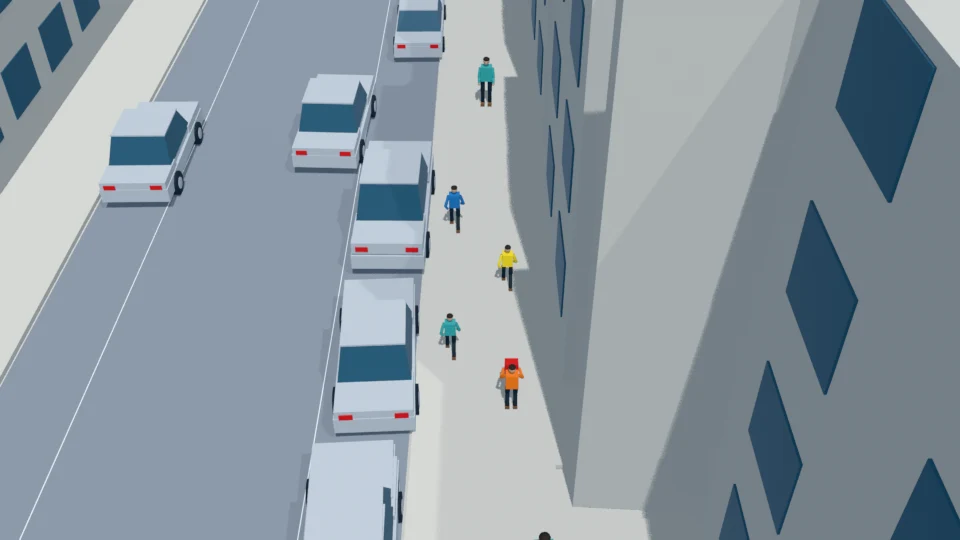
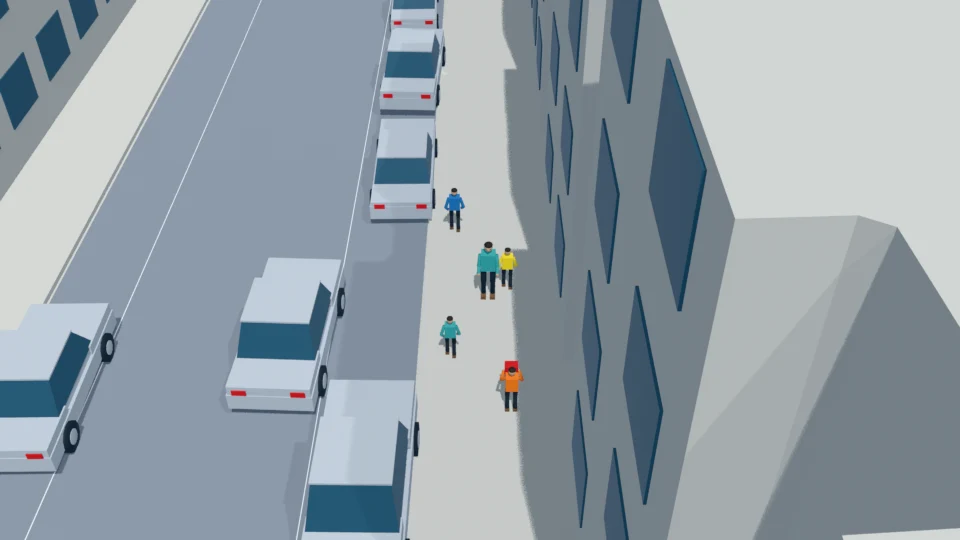
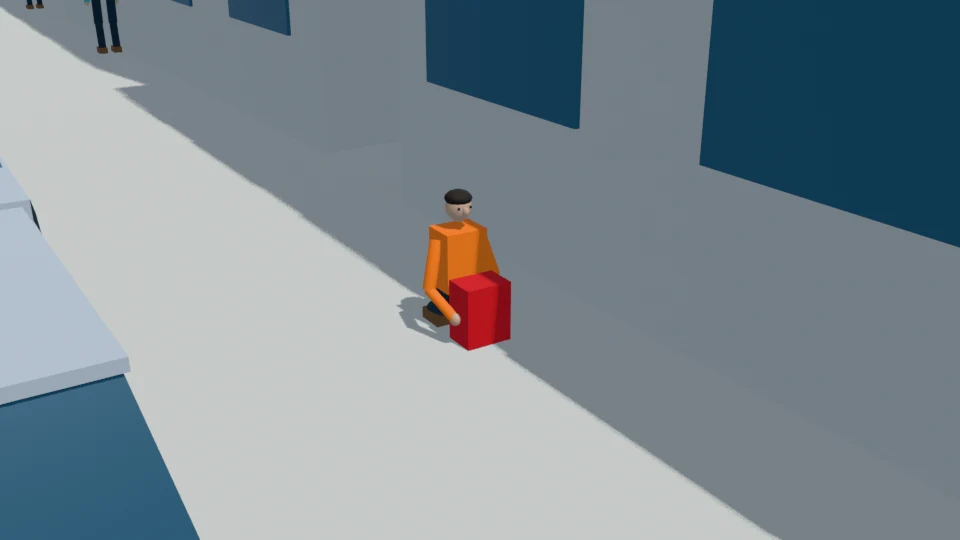
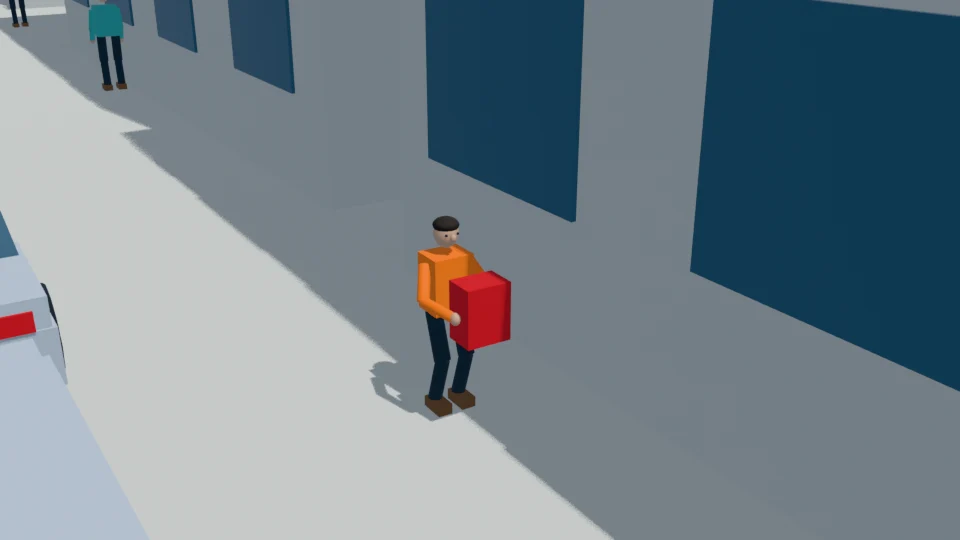
Awaiting your 3D scene approvalFour children play-chase east along the south sidewalk. The trailing child notices a previously dropped backpack, turns back, retrieves it, and walks east to rejoin the waiting group. Nobody enters the roadway.
Original description: 一群孩子在路边的人行道上追逐打闹,整体向东移动,有一个孩子在一段时间之后发现掉落的背包,回头捡起来再继续回到其他孩子中。
Loading the full animated scene…
Critical moments
What to verify
- Require exactly four child actors and one backpack, all persistent from -7 through 40 seconds.
- At every 20 Hz sample, keep all child and backpack footprints inside the supplied south sidewalk polygon; do not add a roadway crossing.
- Maintain at least 0.6 m body clearance between ordinary walkers, including during reunion and group restart.
- Check running cruise speeds of 2 to 4 m/s, walking cruise speeds of 0.6 to 1.7 m/s, bounded acceleration, and zero translation during the two stationary turns.
- Require continuous backpack pickup and attachment at 11 seconds, with no duplicate backpack, ground penetration, or snapping during its attached turn.
- Ego must stop at x=14 and may resume at 33 seconds only after confirming that its complete swept corridor remains clear.
- Human review must approve the full rehearsal, geometry, separation, and original-photo placement before any image generation; these checks are requirements, not reported test results.
Review notes
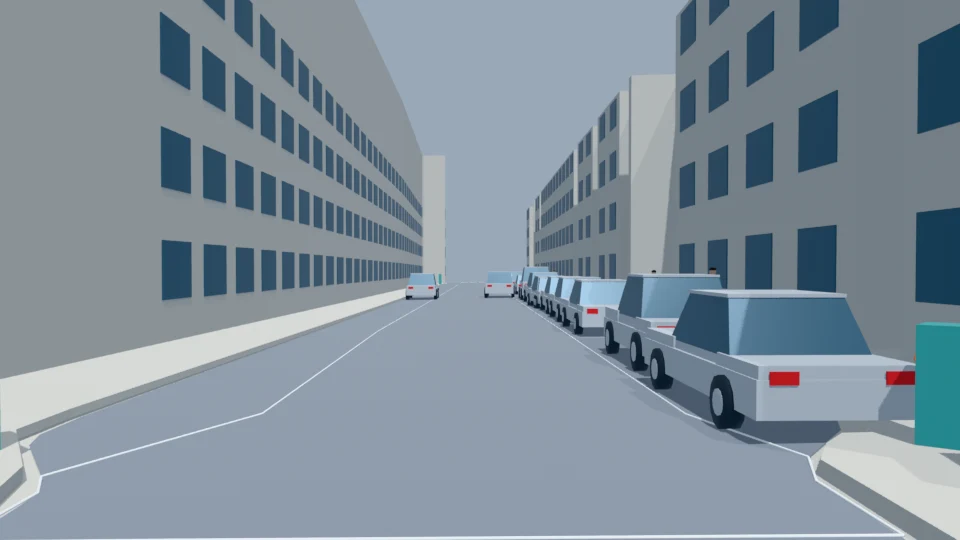
Inspected the corrected event and contact cameras. The children chase along the sidewalk; the trailing child turns back, crouches, retrieves the backpack, and carries it while regrouping. Front-camera visibility is substantially occluded by a parked car, so later images need a suitable time or side-camera selection.
Check action, relative position, facing, posture and visibility. Approximate offsets are acceptable. Sampled visual checks do not prove every contact or continuous collision clearance.
Rendered inspection views
Event, approach and final views rendered from the exact committed Higgsfield Blender source. These are procedural 3D previews, not generated training photographs.
Original NAVSIM camera context
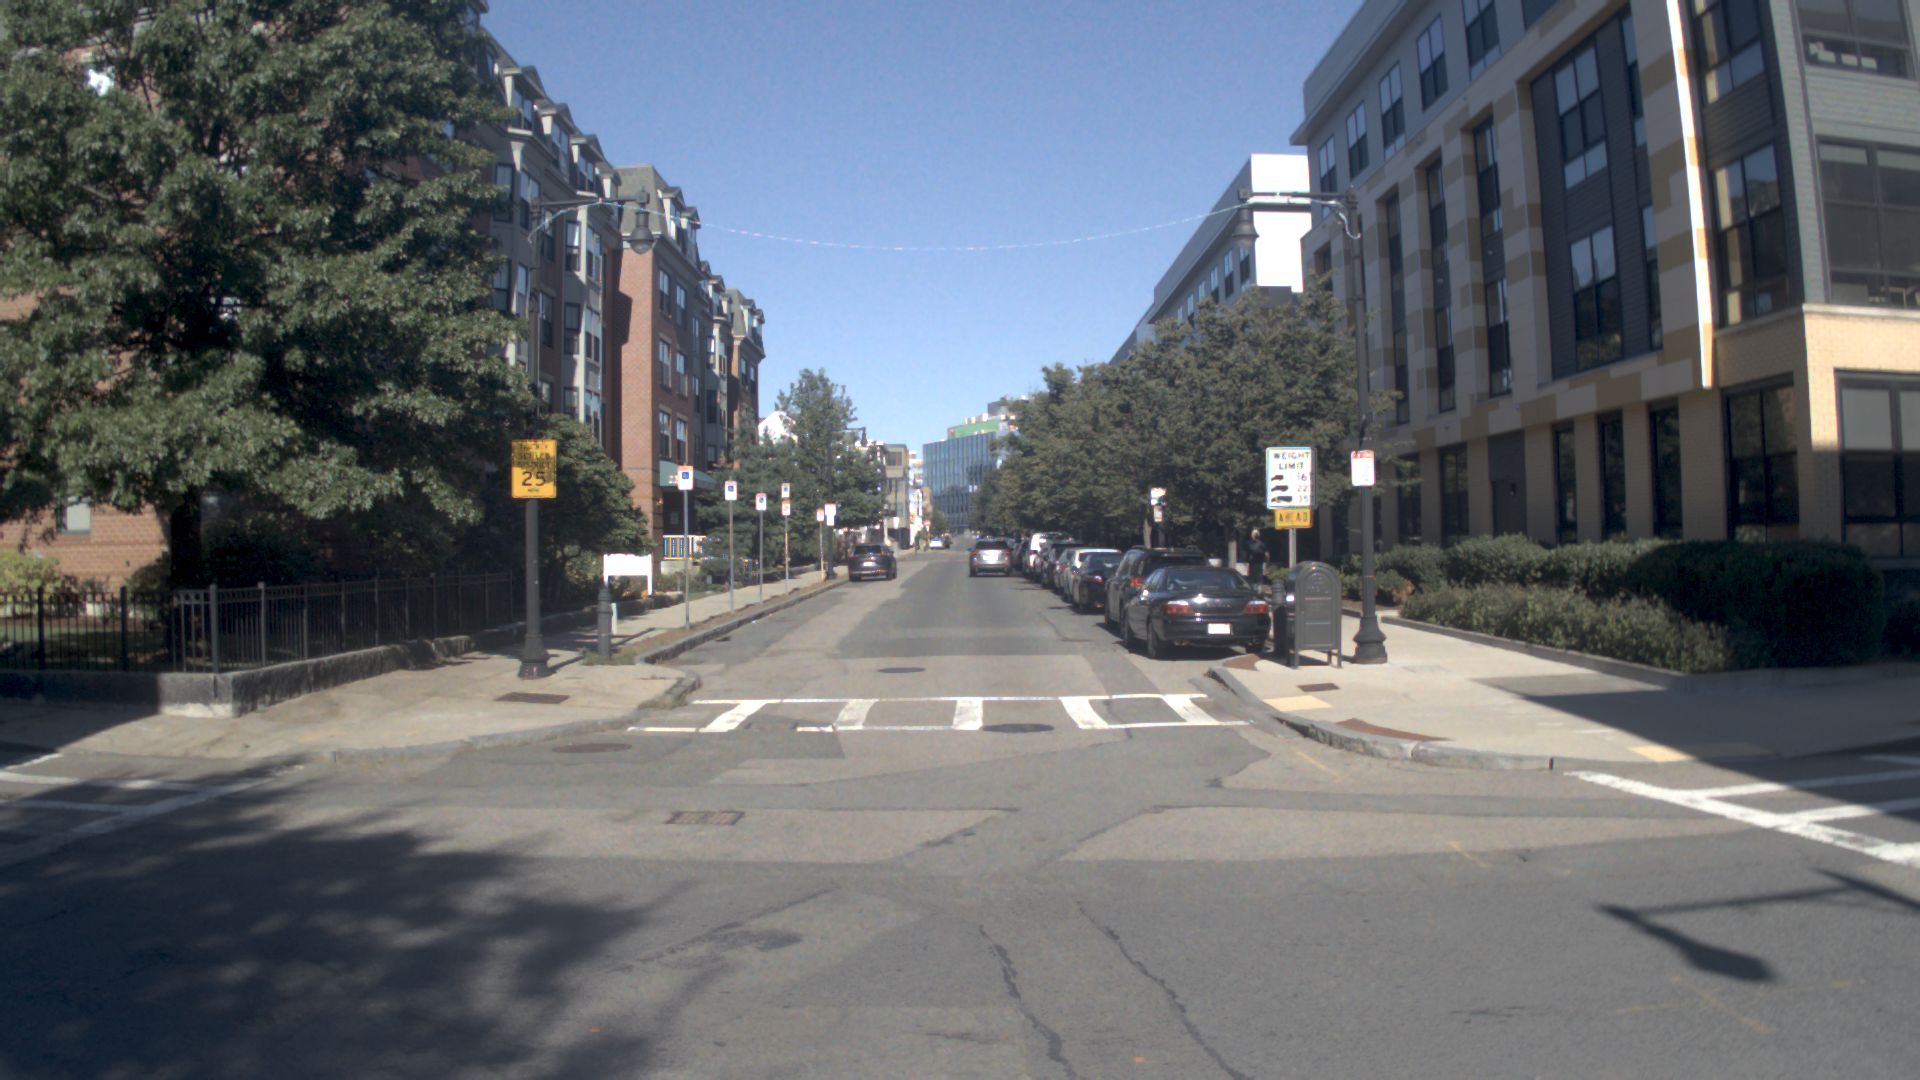
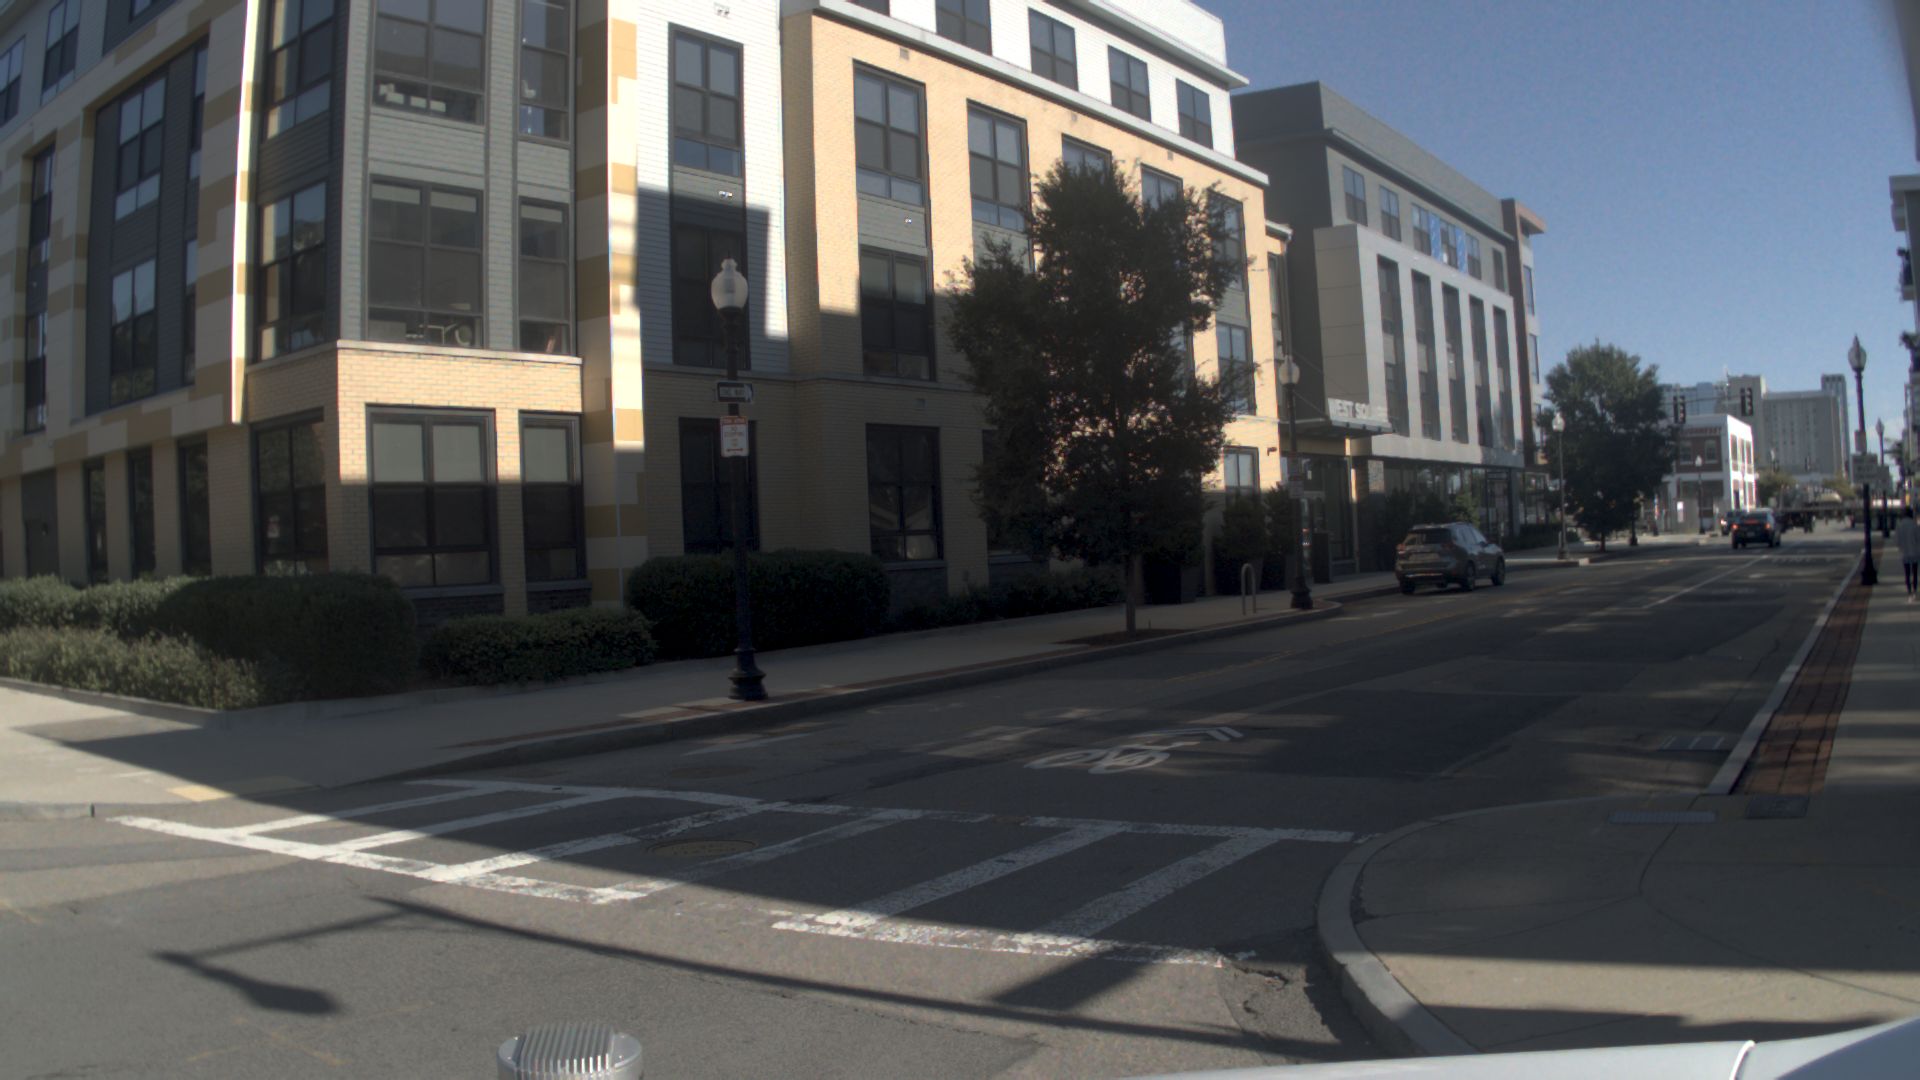
No additional background-vehicle holding corrections were needed. Original photos remain unchanged. Before later inpainting, any overlap with original-photo traffic must be resolved. Background positions in this 3D rehearsal are not an exact replay of the photographs.
After scene approval
The working pipeline will edit each original NAVSIM camera photograph with Image 2.5. Its same-time Higgsfield view will provide position and posture, annotated with facing direction and current speed. Temporal image requests will cover the full event with a 1 Hz base plus critical moments.
Assumptions and source provenance
- Image 1 and the wheelchair map support the broad street, sidewalk, and building context only. All children, motions, coordinates, timing, and backpack placement are counterfactual proposals.
- The unspecified group is instantiated as four children. The backpack was dropped before -7 seconds and is not noticed until 0 seconds; no unshown disappearance or second backpack is implied.
- The selected south sidewalk tracks at y=-5.45 and y=-6.85 lie within the supplied polygons over the authored route.
- Playback is finite and non-looping: -7 through 40 seconds at 20 Hz, including both endpoints, for 941 samples. Use bounded-speed interpolation with explicit stationary turns and no positional overshoot.
- All human roots use z=0 on the mapped support surface. Attached backpack z samples account for the supplied ground-plane slope; attachment transforms take precedence during the attachment interval.
- Ego is implicit rather than a duplicate cast actor. It approaches on y=0 from x=13 at -7 seconds, brakes from 2 m/s to rest at x=14 by -6 seconds, and after release accelerates at no more than 0.75 m/s squared to at most 1.5 m/s.
- Exact static-obstacle footprints are not supplied and require human confirmation. A later Image 2.5 edit must use original Image 1, with this rehearsal supplying positions and postures only; no image generation is authorized by this annotation.
Fresh GPT-6 motion plans use semantic descriptions from the pinned consolidated catalog and NAVSIM environments. No upstream nuPlan vectors, trajectories or images are used. The four source environments are reused; 82 scenario descriptions do not mean 82 independent locations.
Higgsfield revision 1. The portable GLB combines export clips without changing geometry or animation samples.
This review uses Higgsfield revision 1 and the exact exported scene snapshot.
Higgsfield workspace (latest revision) · Download animated GLB · GPT-6 scene plan · Visual review evidence · Motion checks · Approval status